Text Generation Inference (TGI)
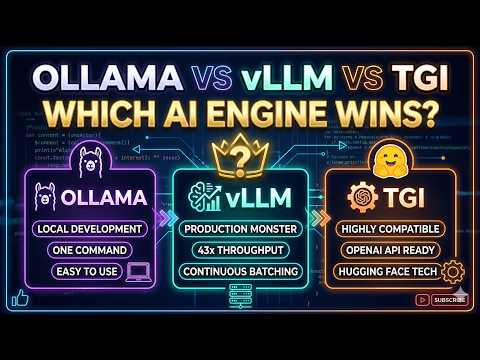
Text Generation Inference (TGI) is a Rust and Python-powered inference server designed for serving large language models at scale. It provides a production-ready HTTP API compatible with OpenAI standards and includes advanced features like dynamic batching, token streaming, continuous batching, quantization (GPTQ, AWQ, EXL2), and multi-GPU tensor parallelism. TGI is optimized for both on-premise and cloud deployments, supporting hardware from NVIDIA, AMD, Intel, and AWS Gaudi accelerators. TGI simplifies the deployment of models from the Hugging Face Hub and the text-generation-inference Docker image. It supports popular architectures like Llama, Falcon, StarCoder, BLOOM, and more. The server handles the complexities of model loading, tokenization, and GPU memory management, allowing developers to focus on application logic rather than infrastructure.
Everything worth knowing about Text Generation Inference (TGI)
The complete picture — from everyday features to the technical detail builders and IT folks dig for.
What it actually does
Who uses it
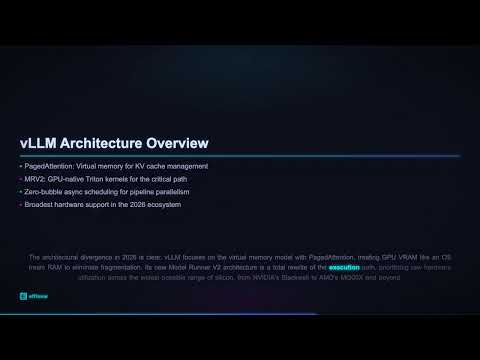
Real use cases, no hype- Optimized for high-throughput LLM inference with FlashAttention and PagedAttention.
- Simple, production-ready Docker image with pre-configured settings.
- Supports a wide range of Hugging Face models out-of-the-box.
- Baked-in token streaming and continuous batching for real-time apps.
- OpenAI-compatible API for drop-in replacements and easy integration.
- Rust-based router and Python server hybrid architecture for performance and flexibility.
- Advanced quantization (GPTQ, AWQ, EXL2, GGUF) and Tensor Parallelism for model sharding.
- Primarily focused on NVIDIA GPUs; CPU inference is not supported.
- Steep learning curve for advanced configuration and custom kernel integration.
- Requires significant VRAM for larger models; no native CPU fallback.
- Limited built-in support for non-text modalities without specific backend extensions.
- Model compatibility can lag behind Hugging Face Transformers releases.
- Nix-based builds and Docker compilation are complex and time-consuming.
The deep-dive specs
FAQ
Includes technical Q&ATraffic Insights
Monthly Visits
—
November 2026
Growth Rate
0%
vs last month
Dominance
0%
in Coding
Top Country
—
Top Countries Breakdown
—
Growth Trend
Stable
Traffic has remained stable.
Text Generation Inference (TGI) Pricing
Text Generation Inference (TGI) uses a unknown pricing structure. Real-time rates, custom enterprise quotas, and plan details are managed directly on their official platform.
Check Pricing on Text Generation Inference (TGI)What the internet actually thinks
Data refreshed weekly. No paid placements.
Leave a Comment
Help others make informed decisions. Your honest feedback shapes the community's understanding of this tool.
Tips for commenting
- •Be specific about features you used
- •Share real use cases and results
- •Mention both pros and cons
- •Keep it honest and constructive
Your comment is published immediately.
No comments yet
Be the first to share your experience with this tool.
Not quite the right fit?
Here's what else is out there.