LanceDB

LanceDB

LanceDB is an open-source, serverless vector database built on the Lance columnar format, designed for AI/ML workloads. It supports multimodal data (text, images, video, audio) with native vector, full-text, and hybrid search capabilities, all queryable with SQL. Key features include a managed cloud version (LanceDB Enterprise), a high-performance columnar storage format optimized for AI, and an embedded library for local development. It's built for massive scale, supporting datasets with billions of vectors and petabytes of data. Targeted at ML engineers, AI developers, and data scientists building applications like RAG, recommendation systems, and computer vision pipelines. It integrates with popular frameworks like PyTorch and LangChain, and powers production systems at companies like Netflix and ByteDance.

Search
Visit website
Added on
Sep 22, 2026
Multimodal LakehouseVector SearchFeature EngineeringModel TrainingLance FormatHybrid Retrieval
Product information

Everything worth knowing about LanceDB

The complete picture — from everyday features to the technical detail builders and IT folks dig for.

Core features

What it actually does

Multimodal Data Lakehouse
Unified platform for managing all AI data (text, images, video, audio) from raw files to production-ready features.
Vector, Full-Text, and Hybrid Search
Unified search with SQL filters for production-ready retrieval across different data types.
Scalable Feature Engineering
Build and scale features with Python UDFs, automatic updates, and no table rewrites.
High-Performance Model Training
Train directly from curated data with up to 70% Model FLOPs Utilization (MFU) and no data movement bottlenecks.
Technical capabilities
Lance Columnar Format
Optimized for object storage metadata, supporting efficient scans, random access, and late materialization for large binary data.
IVF_RQ Vector Indexing
Approximate nearest neighbor search using RaBitQ quantization for high recall and low latency at scale.
Data Versioning and Reproducible Curation
Git-style branching and shallow clone for AI data, enabling versioned curation workflows.
Must watch videos
Intro to LanceDB in 2 Minutes
2:00
Tutorial2:00
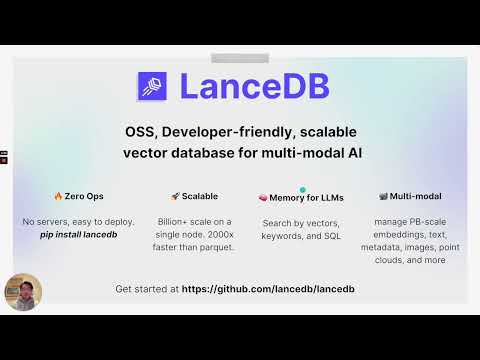
Intro to LanceDB in 2 Minutes
Find us on Github at: https://github.com/lancedb/lancedb LanceDB is backed by Lance format, a Rust-based columnar format that's 2000x faster than parquet for AI use cases. The data format is open-source and available at https://github.com/lancedb/lance This video was first presented at the Essence LLM Developer Virtual Conference on June 1st, 2023
What is RAG? Build a Document AI Agent in 5 Minutes | Vector DB (LanceDB) + Agno + Gemini
7:25
Tutorial7:25
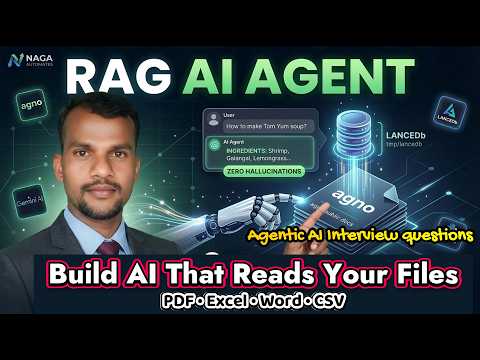
What is RAG? Build a Document AI Agent in 5 Minutes | Vector DB (LanceDB) + Agno + Gemini
Learn how to build a "Chat with PDF" AI Agent using Python! In this tutorial, we dive into the world of RAG (Retrieval-Augmented Generation). While standard web-search agents browse the internet, RAG agents search through your personal, private documents to answer questions accurately without making things up (hallucinating). We are using the Agno Framework to build a Knowledge Base, LanceDB for local vector storage, and the Gemini 1.5 model for reasoning and embeddings. In this video, you will learn: What is RAG and why is it important? Converting text into Vector Embeddings using GeminiEmbedder. Setting up a local LanceDB database without complex installations. Building an Agent that reads, remembers, and extracts data from PDFs. timestamp: 0:00 Introduction 1:00 RAG agent coding 2:30 Main Tutorial 5:40 RAG Agent Demo 6:45 RAG/Agentic AI Interview Questions 🔧 Libraries Used: pip install agno google-genai lancedb pypdf #RAG #agenticai #python #AgnoFramework #geminiai #LanceDB #nagaautomates #coding #artificialintelligence #ChatWithPDF
AI Lakehouse Meetup: Scaling Agents, Iceberg & LanceDB
1:49:34
Tutorial1:49:34
AI Lakehouse Meetup: Scaling Agents, Iceberg & LanceDB
AI Lakehouse Architecture: Multimodal Data, Agents & Federation. Learn how LanceDB, Cloudera, PuppyGraph, and Google Cloud build next-generation AI Lakehouses for multimodal data, autonomous agents, and zero-copy federation. 📌 In this deep-dive technical session: • Multimodal Data Layers: Scaling text, image, and video embeddings with LanceDB. • Autonomous Data Agents: Runtime isolation and copy-on-write semantics on Iceberg. • Graph RAG Traversals: Sub-second relationship search using Cypher & PuppyGraph. • Zero-Copy Cross-Cloud Federation: Querying data split across AWS & Google Cloud. 👉 Subscribe to Cloudera: https://www.youtube.com/channel/UCXY5wm6HlBL_Y_8SDxJNR0g AI Lakehouse Meetup - Bay Area 📅 15th July 2026 📍 Cloudera SanJose Office Join the Cloudera Community to learn more! 👉https://community.cloudera.com Full Playlist: https://www.youtube.com/playlist?list=PLe-h9HrA9qfDR6fcXaJQTmV4wi_1lvHjW *Get Started* 🔹 Request a Demo: https://www.cloudera.com/products/cloudera-data-platform/cdp-demos.html?utm_medium=social-organic&utm_source=youtube&keyplay=cross&utm_campaign=Other---AlwaysOn-GLOBAL-WS-Website-CDP-Demo-Request&cid=7012H000001Z3MrQAK&utm_content=youtube-cta 🔹 Customer Success Stories: https://www.cloudera.com/customers.html?&utm_medium=social-organic&utm_source=youtube&keyplay=cross&utm_campaign=Other---FY27-Global-Always-On-Youtube&cid=UNGATED&utm_content=youtube-cta 🔹 Read the Cloudera blog: https://www.cloudera.com/blog.html *Resources:* Hear more from our customers: https://www.youtube.com/playlist?list=PLe-h9HrA9qfABGzjKR86Sycoyq83EjLl9 Watch Demos: https://www.youtube.com/playlist?list=PLe-h9HrA9qfCZIH6ji5hxKucwXi0xvBSi Chapters: 0:00:00 AI Lakehouse Meetup Opening 0:00:37 What is LanceDB Multimodal Format 0:14:45 How Netflix Scales Media Lakehouses 0:27:38 Data Agents in Iceberg Lakehouses 0:31:55 How Autonomous Agents Query Storage 0:45:20 Governance Rules for Data Agents 0:51:20 How GraphRAG Enhances Agent Context 1:00:05 Zero-ETL Virtual Graph Traversals 1:21:40 How to Build Cross-Cloud Lakehouses 1:33:40 [Demo] Zero-Copy Cloud Federation 1:41:40 Cross-Cloud Performance Q&A 🔔 Subscribe to stay ahead of the curve with the latest in data strategy, open architectures, and enterprise AI innovations. https://www.youtube.com/channel/UCXY5wm6HlBL_Y_8SDxJNR0g https://www.cloudera.com LinkedIn ► https://www.linkedin.com/company/cloudera Facebook ► https://www.facebook.com/cloudera/ X ► https://twitter.com/cloudera Spotify ► https://open.spotify.com/show/102S8zoZR6nmZV0HxZlxZu #ApacheIceberg #LanceDB #DataEngineering #GraphRAG #Cloudera #lakehouse #datalakehouse

Who uses it

Real use cases, no hype
Multimodal AI Training
Load, shuffle, and stream large-scale image, video, and text datasets directly into PyTorch or other frameworks with minimal I/O bottleneck.
RAG & Semantic Search
Power retrieval-augmented generation with fast, filtered vector search and full-text retrieval across massive knowledge bases.
Data Curation & Deduplication
Clean and prepare massive datasets by finding optimal distributions, removing duplicates, and surfacing edge cases efficiently.
Feature Engineering at Scale
Build and update ML features with Python UDFs, automatic materialization, and no table rewrites for production pipelines.
Agent Memory & State
Provide durable, semantic memory for AI agents with conflict resolution and confidence-gated recall across sessions.
Autonomous Vehicle Data Pipelines
Ingest and process high-frequency sensor data (LiDAR, camera) for perception model training and fleet data analysis.
Cost-Effective Vector Search
Run high-throughput vector search at a fraction of the cost of traditional full-service solutions like OpenSearch.
What's great
  • Blazing-fast vector search at 10B+ scale with RaBitQ and HNSW.
  • Unified vector, full-text, and hybrid search with SQL filters.
  • Direct training from curated data with up to 70% MFU.
  • Seamless Python and Spark ecosystem integration.
  • Embedded, serverless architecture for local development.
Technical strengths
  • Lance format delivers superior random-access I/O for multimodal data.
  • RaBitQ quantization hits 96% recall without refine overhead.
Where it falls short
  • Steeper learning curve than simple key-value vector stores.
  • Enterprise features require a separate, paid tier.
  • Documentation, while extensive, can be dense to navigate.
Technical limitations
  • Full performance benefits require adoption of the Lance format.
  • Advanced indexing (IVF, HNSW) needs careful tuning for optimal results.
For technical folks

The deep-dive specs

FAQ

Includes technical Q&A
LanceDB is an embedded, serverless database built on the Lance columnar format. It runs in-process (like SQLite for vectors) or scales to a cloud service, focusing on multimodal data and direct integration with ML training pipelines, unlike dedicated database services.

Traffic Insights

Monthly Visits

—

October 2026

Growth Rate

0%

vs last month

Dominance

0%

in Search

Top Country

—

Top Countries Breakdown

—

Growth Trend

Stable

Traffic has remained stable.

Pricing overview
Freemium Pricing

LanceDB Pricing

LanceDB uses a freemium pricing structure. Real-time rates, custom enterprise quotas, and plan details are managed directly on their official platform.

Check Pricing on LanceDB
Reviews

What the internet actually thinks

Data refreshed weekly. No paid placements.

Trustpilot
Not reviewed yet
G2
G2
Not reviewed yet
C
Capterra
Not reviewed yet
Product Hunt
Not reviewed yet
COMMUNITY COMMENTS

Leave a Comment

Help others make informed decisions. Your honest feedback shapes the community's understanding of this tool.

Tips for commenting

  • •Be specific about features you used
  • •Share real use cases and results
  • •Mention both pros and cons
  • •Keep it honest and constructive
to leave a comment

Your comment is published immediately.

Filter:
Sort:

No comments yet

Be the first to share your experience with this tool.

Alternatives

Not quite the right fit?

Here's what else is out there.