Hume AI

Hume AI

Hume AI provides APIs and tools for building emotionally intelligent voice AI systems. Its core offerings include the Empathic Voice Interface (EVI) for real-time, expressive speech-to-speech interaction and Octave Text-to-Speech (TTS) for context-aware, nuanced speech synthesis. The platform is built on a research foundation of multimodal emotional intelligence, measuring 48+ emotions across 50+ languages. Key capabilities include real-time expression measurement, voice design and cloning, human feedback APIs for evaluation at scale, and simulation platforms for testing voice AI scenarios. It targets developers, AI researchers, and product teams building conversational agents, digital companions, creative tools, and customer support systems that require high emotional intelligence and natural voice quality.

Audio Generation
Visit website
Added on
Sep 21, 2026
Monthly Visits
220.7K
Emotional Voice AIOctave TTSEVI Real-timeVoice CloningExpression APISOC 2WebSocket API
Product information

Everything worth knowing about Hume AI

The complete picture — from everyday features to the technical detail builders and IT folks dig for.

Core features

What it actually does

Empathic Voice Interface (EVI)
Real-time emotionally intelligent voice AI that measures vocal modulations and responds with appropriate prosody and timing.
Octave Text-to-Speech (TTS)
Expressive speech synthesis using a speech-language model that understands context and meaning for natural, nuanced narration.
Voice Design & Cloning
Create custom voices from descriptive prompts or clone a voice from a sample for consistent persona across TTS and EVI.
Real-Time Expression Measurement
Analyze speech across 48+ emotion categories and 50+ languages with over 600 output metrics via API.
Technical capabilities
Kairos Simulation & Evaluation Platform
Auto-generate and run evaluation scenarios from real-world use cases to test and measure voice AI performance.
Speech-Language Model Architecture
Unified model training on millions of interactions that combines language modeling and text-to-speech generation for improved EQ and alignment.
Must watch videos
Real World VoiceEQ: a benchmark for measuring the human quality of voice AI
2:24
Tutorial2:24
Real World VoiceEQ: a benchmark for measuring the human quality of voice AI
Today Hume is introducing Real World VoiceEQ: a benchmark for measuring the human quality of voice AI across 40+ proprietary and open-source models, 15+ dimensions, and 60+ metrics—developed from more than 1 million individual human ratings. The biggest takeaway: there is no single “best” voice model. The field is becoming specialized. Some models are strong at expressive speech. Others are better at precision. Some understand emotion but struggle to respond naturally. Voice models are getting better at speaking than truly listening. Many systems still reason from transcripts instead of vocal cues like tone, pacing, hesitation, and emphasis. That is a major gap for real-world voice agents. A confident “yeah” and a hesitant “…yeah” can mean very different things responding to a fraud alert or weighing health advice. This is why voice AI needs evaluation that looks beyond words. Traditional benchmarks are starting to overestimate real-world performance. Models can perform well in clean test settings, then struggle with accented speech, noisy environments, overlapping speakers, emotional expression, and long conversations. Speech-to-speech remains one of the least mature frontiers in voice AI. Some systems recognize emotion well but do not respond naturally. Others sound fluid but miss the emotional context. Understanding and responding are still separate capabilities. Human evaluation remains essential for voice AI. Automated judges can help, but voice quality, emotional fit, believability, and conversational appropriateness are ultimately experienced by people. The next phase of voice AI will need a measurement layer: public benchmarks, private evaluations, and production monitoring that show how models perform in the real world, not just under ideal test conditions.
Introducing TADA: Fast, Reliable Speech Generation Through Text-Acoustic Synchronization
0:55
Tutorial0:55
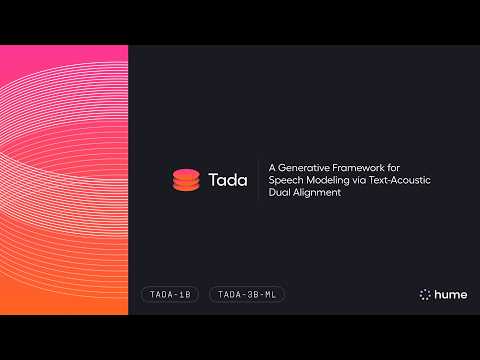
Introducing TADA: Fast, Reliable Speech Generation Through Text-Acoustic Synchronization
The most pressing challenges with speech LLMs today are hallucination and high latency. That’s why we’re open-sourcing TADA: a speech-language model that generates text and audio in one synchronized stream to reduce token-level hallucinations and improve latency. → Zero content hallucinations across 1,000+ test samples → 5x faster than similar-grade LLM-based TTS → Fit much longer audio: 2,048 tokens cover, ~70 seconds in conventional systems VS. ~700 seconds with TADA. → Free transcript alongside audio with no added latency. Try the model: 1B (English): huggingface.co/HumeAI/tada-1b 3B (multilingual): huggingface.co/HumeAI/tada-3b-ml Demo: huggingface.co/spaces/HumeAI/tada GitHub: github.com/HumeAI/tada arXiv: https://arxiv.org/abs/2602.23068 Learn more about TADA: https://www.hume.ai/blog/opensource-tada
Hume AI TADA Open Source TTS Model Demo
1:20
Tutorial1:20
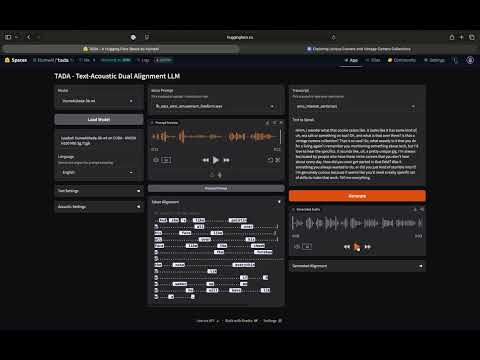
Hume AI TADA Open Source TTS Model Demo
Hume AI TADA Open Source TTS Model Demo Find out more at https://www.hume.ai/blog/opensource-tada

Who uses it

Real use cases, no hype
Emotionally Intelligent Digital Assistants
Build voice assistants that detect and respond to user emotion in real-time for improved engagement and reduced frustration.
Expressive Content Narration
Generate natural, context-aware voiceovers for videos, audiobooks, and podcasts using the Octave TTS model.
Voice AI Evaluation & Benchmarking
Run realistic conversation simulations and human studies to measure and improve voice AI performance.
Real-time Speech-to-Speech Agents
Create interactive, empathetic characters for companionship, coaching, or customer service with low latency.
Voice Cloning for Custom Personas
Design and deploy unique, branded voices for applications, games, or virtual experiences.
Multilingual Emotion Analysis
Analyze vocal expressions across 50+ languages and 600+ voice descriptors for global applications.
What's great
  • Research-backed emotional intelligence models with 48+ emotion categories.
  • Unified platform for data collection, simulation, measurement, and human feedback.
  • Real-time voice interaction (EVI) and expressive TTS (Octave) in one ecosystem.
  • Custom voice design and cloning capabilities with unlimited use across plans.
Technical strengths
  • Built-in agent-to-agent and human-to-agent conversation simulation for evaluation.
  • Speech-language model architecture unifies language modeling and TTS for better prosody and EQ.
Where it falls short
  • Pricing scales quickly; high-concurrency and commercial use requires Pro tier or above.
  • Free tier is very limited (5 EVI minutes, 15 RPM) - more of a trial than a dev environment.
  • Support is primarily Discord-based for all but the Enterprise plan.
  • Core evaluation tools (Kairos, Human Feedback) require direct sales contact, not self-serve.
Technical limitations
  • WebSocket-based EVI integration can be complex for rapid prototyping.
For technical folks

The deep-dive specs

FAQ

Includes technical Q&A
Octave TTS synthesizes expressive speech from text. EVI (Empathic Voice Interface) is a full speech-to-speech system that listens, understands emotion in real-time, and responds with its own expressive speech, powered by a unified speech-language model.

Traffic Insights

Monthly Visits

220.7K

November 2026

Growth Rate

0%

vs last month

Dominance

0%

in Audio Generation

Top Country

United States

32% of traffic

Top Countries Breakdown

United States
32%
India
9%
Bangladesh
6%
Egypt
6%
Germany
3%

Growth Trend

Stable

Traffic has remained stable.

Honest pricing

No sneaky tiers, no “contact sales”

Here's who each plan is actually for — and where the hidden charges might hit.

Free
Free

Individuals

  • 10000 TTS characters/month
  • 5 EVI minutes/month
  • 15 RPM
  • Unlimited voice cloning
  • 1 concurrent connection
  • Discord support.
Starter
$3/mo

Individuals

  • 30000 TTS characters/month
  • 40 EVI minutes/month
  • 15 RPM
  • Unlimited voice cloning
  • 5 concurrent connections
  • Discord support.
Creator
Most picked
$14/mo

Individuals

  • 140000 TTS characters/month
  • 200 EVI minutes/month
  • 75 RPM
  • $0.15/1
  • 000 additional TTS characters
  • Unlimited voice cloning
Pro
$70/mo

Teams

  • 1
  • 000000 TTS characters/month
  • 200 EVI minutes/month
  • 75 RPM
  • $0.12/1
  • 000 additional TTS characters
Enterprise
Custom

Enterprise

  • Custom TTS characters
  • Custom EVI minutes
  • Custom RPM
  • Custom additional costs
  • Unlimited voice cloning & API access
  • Unlimited concurrent connections
  • Unlimited team seats
View Full Plans & Pricing on Hume AI

Official pricing, checkout, and plan upgrades are handled directly on hume.ai.

Reviews

What the internet actually thinks

Data refreshed weekly. No paid placements.

Trustpilot
Not reviewed yet
G2
G2
Not reviewed yet
C
Capterra
Not reviewed yet
Product Hunt
Not reviewed yet
COMMUNITY COMMENTS

Leave a Comment

Help others make informed decisions. Your honest feedback shapes the community's understanding of this tool.

Tips for commenting

  • •Be specific about features you used
  • •Share real use cases and results
  • •Mention both pros and cons
  • •Keep it honest and constructive
to leave a comment

Your comment is published immediately.

Filter:
Sort:

No comments yet

Be the first to share your experience with this tool.

Alternatives

Not quite the right fit?

Here's what else is out there.