Directory/Search/AI Benchmarking/Artificial Analysis
Artificial Analysis

Artificial Analysis

Artificial Analysis is an independent AI benchmarking and analysis platform. It evaluates language, image, video, and speech models with its own methodology — the Intelligence Index (9 evals incl. Terminal-Bench, FrontierCode, HLE-Diamond), Coding Agent Index, Cyber Index, Decision Index, plus blind-vote Image and Video Arenas — and ranks models by quality, speed, and cost per task. Beyond leaderboards, it ships practical tooling: the Model Recommender for use-case-specific picks, Optima for building custom benchmarks, MicroEvals, and a Data Playground. API and data access exist for teams that want the raw numbers. The point is simple: pick the cheapest model that actually does your job, instead of defaulting to whatever tops a hype list. Built for developers, ML engineers, researchers, and technical founders evaluating model/provider tradeoffs. It is a benchmarking and analysis layer, not a model provider — it sells you the truth about models, not the models.

Search
Visit website
Added on
Nov 4, 2026
LLM leaderboardsImage ArenaVideo ArenaIntelligence IndexBlind Elo votingCost per taskSpeed benchmarksAPI data access
Product information

Everything worth knowing about Artificial Analysis

The complete picture — from everyday features to the technical detail builders and IT folks dig for.

Core features

What it actually does

Intelligence Index Leaderboard
Ranks 700+ language models on a single composite score built from independent evaluations, with filters for open weights vs proprietary, text-only vs multimodal, and country of origin.
Image & Video Arenas
Blind human-preference Elo leaderboards for text-to-image, image editing, text-to-video, image-to-video and video editing, with sample counts and confidence intervals so you can judge how trustworthy each rank is.
Cost & Speed Benchmarking
Every model is priced per task, per 1,000 images, or per minute of video, alongside time-per-task and output tokens. The Pareto charts show which models actually sit in the attractive quadrant.
Model Recommender
Get personalised model recommendations optimised for your own weighting of intelligence, speed and cost instead of guessing from a single headline rank.
Data Access & API
Programmatic access to the underlying benchmark data via API and data playground, aimed at teams wiring model-selection logic into their own tooling.
Technical capabilities
Composite Index Methodology
Indexes are versioned and composable: Intelligence Index v5.0.1 combines 9 evaluations (AA-Briefcase v1.1, AutomationBench-AA, Terminal-Bench 4.0, FrontierCode 2.0, AA-Omniscience v1.1, GDP.pdf, HLE-Diamond, CritPt v2 Hard Subset, Terminal-Bench-Science 0.1), while the Coding Agent Index v2.0 and Cyber Index v1 each blend their own benchmark sets.
Provider-Level Endpoint Testing
Benchmarks are run against live API endpoints, measuring speed, latency and endpoint accuracy per provider for the same model — because the same model served by two providers is not the same product.
Must watch videos
Build your own AI evals with Optima (end-to-end walkthrough)
17:43
Tutorial17:43
Build your own AI evals with Optima (end-to-end walkthrough)
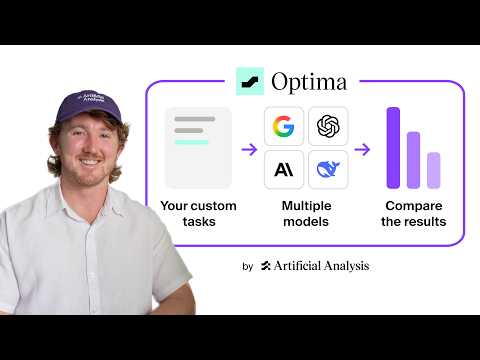
Build your own custom AI benchmarks with Optima by Artificial Analysis. Standardized benchmarks measure general model capability, but they can't tell you which model is right for your specific use case. Optima lets you build custom benchmarks around your own tasks, so you can compare models on performance, cost, and time efficiency. Try Optima: https://artificialanalysis.ai/optima Timestamps: 0:00 - Intro 1:19 - Creating a custom benchmark with Optima 3:17 - Choosing the type of evaluation to make 4:46 - Reviewing our task criteria 6:46 - Inspecting our example tasks 8:09 - Letting Optima build our task set 9:49 - Choosing models to run our custom tasks 11:25 - Running 6 models on our custom tasks 12:04 - Grading our candidate model outputs 12:38 - Optima pricing overview 13:01 - Viewing and comparing the performance, speed and cost tradeoffs
Introducing the Artificial Analysis Intelligence Index v4.1
2:41
Tutorial2:41
Introducing the Artificial Analysis Intelligence Index v4.1
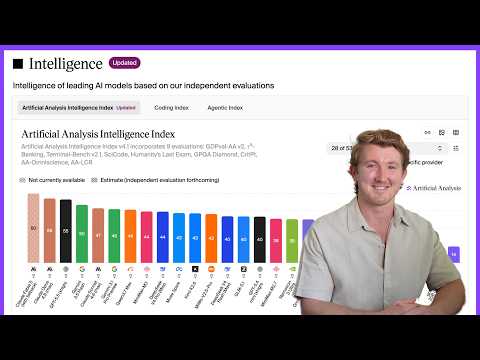
The Artificial Analysis Intelligence Index is our synthesis metric for assessing model intelligence and tracking AI progress. Today we announced v4.1 with changes listed below. Links: Artificial Analysis Intelligence Index - https://artificialanalysis.ai/ Artificial Analysis Intelligence Index Methodology - https://artificialanalysis.ai/methodology/intelligence-benchmarking Intelligence Index v4.1 brings the following updates: 1. We upgraded three evaluations, removed one, and reweighted the Intelligence Index: ➤ Upgraded Terminal-Bench Hard to Terminal-Bench 2.1 and τ²-Bench Telecom to τ³-Bench Banking. Both move to newer, more robust task sets with harder, more realistic agentic scenarios that better separate frontier models ➤ Upgraded GDPval-AA to GDPval-AA v2. The upgrade re-baselines Elo to human performance at 1000, introduces a rotating panel of frontier-model judges, and raises the turn limit from 100 to 250 for longer-horizon agent trajectories ➤ Removed IFBench due to saturation. The benchmark no longer distinguishes frontier models sufficiently, so we have removed it from the Intelligence Index. We will continue to run it and publish results on new model releases 2. Cost per Task, Time per Task, and Tokens per Task: Three new per-task metrics, reported for every model and based on the Intelligence Index. We take the total cost, total time, and total output tokens for a model to run the Intelligence Index and divide by the number of tasks across its evaluations, giving the average cost, time, and output tokens to complete a single Intelligence Index task 3. Cached input token reporting: We now report cached input tokens and their impact on cost, including the cost to run the Intelligence Index, to better reflect the real cost of running each model Timestamps: 0:00 - Intro 0:26 - Evaluation and Benchmark Changes 1:00 - Cost per Task, Time per Task, Tokens per Task additional metrics 1:39 - Cache pricing breakdown 1:54 - Leading overall models 2:05 - Leading open-source models 2:19 - Methodology and outro
How do you measure a model's capability to do economically valuable tasks? | GDPval-AA
4:10
Tutorial4:10
How do you measure a model's capability to do economically valuable tasks? | GDPval-AA
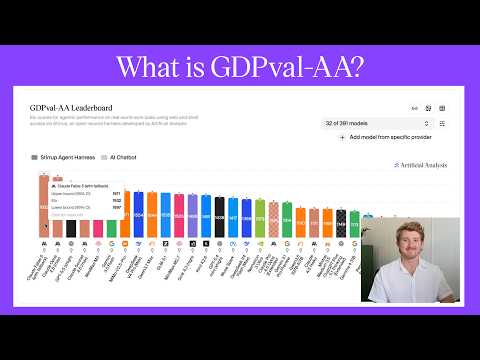
GDPval-AA v2 is Artificial Analysis' evaluation framework for OpenAI's GDPval dataset. It assesses language models' capabilities on 220 economically valuable tasks, covering 44 occupations across 9 sectors contributing to GDP in the United States. **Update:** We've just released GDPval-AA-v2 with upgraded evaluations including a panel of judges, the main methodologies in this video still hold but they've been improved with v2. All links below lead to the updated results. Links: • GDPval-AA v2 leaderboard - https://artificialanalysis.ai/evaluations/gdpval-aa • GDPval-AA v2 methodology - https://artificialanalysis.ai/methodology/intelligence-benchmarking#gdpval-aa • GDPval Public Dataset - https://huggingface.co/datasets/openai/gdpval • GDPval blog post by OpenAI - https://openai.com/index/gdpval/ • GDPval paper by OpenAI - https://arxiv.org/abs/2510.04374 Timestamps: 0:00 - Intro 0:04 - Task Breakdown 0:24 - GDPval-AA mentions in the wild 0:31 - GDPval-AA Leaderboard (as of June 12 2026) 0:53 - GDPval-AA Example Tasks 1:18 - GDPval-AA Implementation 2:06 - Comparing Elo Scores 2:40 - Cost and Token Usage 3:22 - Extra Resources

Who uses it

Real use cases, no hype
Model Selection
Pick the right LLM for your use case using intelligence, speed and cost trade-offs instead of vibes.
Cost Optimization
Find cheaper models that hold quality, using cost-per-task rather than per-token sticker price.
Coding Agent Evaluation
Compare coding agents on FrontierCode, Terminal-Bench and SWE-Atlas before wiring one into CI.
Image & Video Model Picking
Blind-vote Elo rankings plus per-1,000-image and per-minute API pricing for generative media.
Vendor & Procurement Decisions
Independent numbers to justify a model or provider choice to finance and legal.
Market Tracking
Changelog and Progress Index keep you current on the weekly model firehose.
Data Access & Research
Pull underlying benchmark data via API for internal dashboards or academic work.
What's great
  • Genuinely independent — vendors don't pay for placement
  • Intelligence, speed and cost side-by-side in one view
  • Covers text, image, video, speech and coding agents
  • Free leaderboards with no login required
Technical strengths
  • Token-level cost breakdown: input, cache hit/write, reasoning, output
  • Arena Elo from blind human votes with published confidence intervals
  • Raw data available via API for your own pipelines
Where it falls short
  • Deep data and exports sit behind Premium
  • Benchmarks are proxies — not your workload
  • No free sandbox to run your own prompts
  • Several top models listed as 'no publicly available API'
Technical limitations
  • Composite index hides which sub-evaluation a model failed
  • Arena Elo carries ±10–15 point intervals — small gaps are noise
  • Index version bumps (v5) break year-over-year comparisons
For technical folks

The deep-dive specs

Intelligence Index Version
v5.0.1
Evaluations in Intelligence Index
9 (AA-Briefcase v1.1, AutomationBench-AA, Terminal-Bench 4.0, FrontierCode 2.0, AA-Omniscience v1.1, GDP.pdf, HLE-Diamond, CritPt v2 Hard Subset, Terminal-Bench-Science 0.1)
Models Benchmarked
722 language models, 101 image models, 29 video models
Coding Agent Index Version
v2.0 (FrontierCode v1.1, Terminal-Bench 4.0, SWE-Atlas-QnA-AA)
Cyber Index Version
v1 (CWE-Bench-AA, DeepsecBench-AA, CyberGym-E2E-AA)
Performance Benchmarking Methodology
v3.0.0
Image Pricing Basis
Cost per 1,000 images at 1024x1024, model default settings
Video Pricing Basis
Cost per minute of video at 1080p where offered

FAQ

Includes technical Q&A
An independent AI benchmarking and analysis company. It benchmarks models and providers so you can choose the right AI technology for your use case and keep up with a fast-moving landscape.

Traffic Insights

Monthly Visits

—

November 2026

Growth Rate

0%

vs last month

Dominance

0%

in Search

Top Country

—

Top Countries Breakdown

—

Growth Trend

Stable

Traffic has remained stable.

Pricing overview
Freemium Pricing

Artificial Analysis Pricing

Artificial Analysis uses a freemium pricing structure. Real-time rates, custom enterprise quotas, and plan details are managed directly on their official platform.

Check Pricing on Artificial Analysis
Reviews

What the internet actually thinks

Data refreshed weekly. No paid placements.

Trustpilot
Not reviewed yet
G2
G2
Not reviewed yet
C
Capterra
Not reviewed yet
Product Hunt
Not reviewed yet
COMMUNITY COMMENTS

Leave a Comment

Help others make informed decisions. Your honest feedback shapes the community's understanding of this tool.

Tips for commenting

  • •Be specific about features you used
  • •Share real use cases and results
  • •Mention both pros and cons
  • •Keep it honest and constructive
to leave a comment

Your comment is published immediately.

Filter:
Sort:

No comments yet

Be the first to share your experience with this tool.

Alternatives

Not quite the right fit?

Here's what else is out there.